Skip to main contentSkip to navigation

NAS Data Recovery for Synology and QNAP Systems

We recover failed NAS arrays with an image-first workflow: member-by-member imaging, offline reconstruction, and recovery from the clone. Free evaluation. No data = no charge.

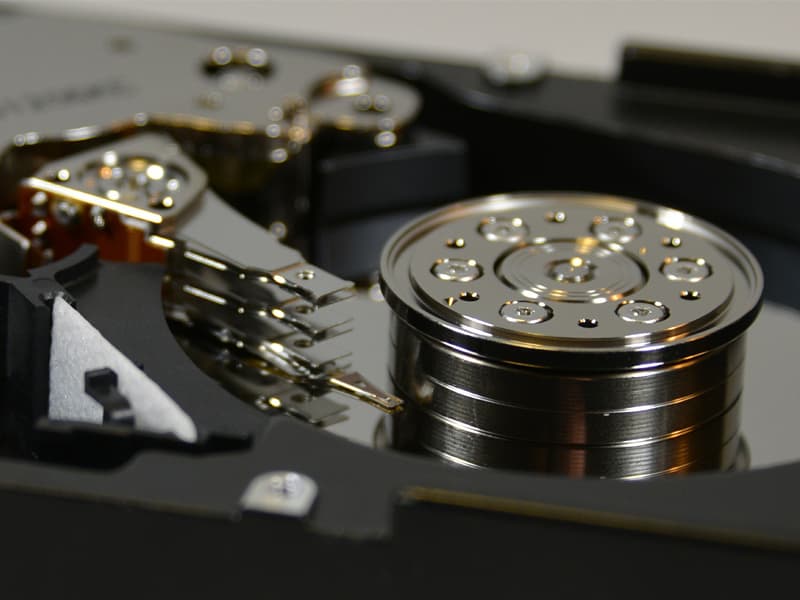
Open hard drive showing the platter stack and head stack
Author
Louis Rossmann
Written by
Louis Rossmann
Founder & Chief Technician
Updated June 2, 2026
15 min read
Call (512) 212-9111No data, no recovery feeFree evaluation, no diagnostic fees
No Data = No Charge
In-House Austin Lab
Nationwide Mail-In
Quick Answer

What Is NAS Data Recovery?

NAS data recovery is the in-house imaging and offline reconstruction of failed Synology, QNAP, Buffalo, TerraMaster, and unRAID arrays. We image each member on PC-3000 or DeepSpar hardware at our Austin, TX lab and rebuild the array from the clones. Free evaluation, no diagnostic fee.

Our lab

Who Images Your NAS Drives, and on What Hardware?

We do, in our own Austin, TX lab, in-house since 2008, one location with no franchises and no outsourcing. We image every member drive that reaches us on PC-3000 Portable III or DeepSpar Disk Imager hardware, and no drive goes to a third party. The clones land on fresh destination media, and we run the reconstruction on the clones.

Once every member is cloned, the array is reconstructed offline from the images, not from your live NAS. For Synology that means reassembling the same Linux stack the box already runs: SHR is mdadm software RAID plus LVM plus Btrfs or ext4, and it mounts read-only on a stock Linux workstation without a single piece of Synology hardware.

For striped hardware arrays we destripe and assemble the members with Data Extractor Express RAID Edition. Because the reconstruction runs on copies, a wrong geometry guess costs a re-run instead of your data.

RAID buys you availability, not a backup. A second member failing mid-rebuild, a firmware update that corrupts the array metadata, or an accidental volume delete takes the whole pool out at once.

Rebuild and enclosure

What Does a NAS Rebuild Do to Your Surviving Drives?

On a RAID 5 or RAID 6 set run by Linux software RAID (the mdadm tool behind Synology DSM & QNAP QTS), the rebuild recreates the failed drive's data on the replacement by doing parity calculations across the surviving drives. A RAID 1 rebuild copies a working mirror, & a RAID 10 rebuild copies the originals. When md hits a read error, it tries to overwrite the bad block with the correct data from elsewhere. The Repair button in DSM & a rebuild in QTS both start that process, & so does SHR, which builds ordinary mdadm RAID 1 & RAID 5 sets under its volume.

The danger is the sustained read. The survivors share the failed drive's power-on hours & operating environment, & a sustained full-surface read pushes an already-marginal sibling into mechanical failure, such as a head crash. On RAID 5, that second failure turns a degraded array into a failed one.

Consumer drives carry a worst-case rating of one unrecoverable read error per 1014 bits read, roughly 12.5 TB, so a long rebuild raises the odds of hitting a latent bad sector. What happens next depends on the stack: mdadm logs the sector in its Bad Block Log & finishes, ZFS finishes & names the damaged file, & low-end consumer hardware RAID aborts the rebuild.

Drive-managed SMR drives fail differently. Sustained rebuild writes fill their small CMR cache, the drive stalls while it rewrites shingled bands, & the NAS ejects a physically healthy member as dead, which is why drive-managed SMR drives are unsafe in a NAS array.

If the data is irreplaceable & you don't have a verified backup, image every member first, then run every reconstruction attempt against the clones. With a verified, current backup, a monitored rebuild is standard practice. If a rebuild already failed partway, recovery after a failed NAS rebuild starts from the same imaging step.

Do You Need to Ship the NAS Enclosure?

Usually not. Which drive belongs to which array, & in which slot, is written on the drives. On Synology DSM & QNAP QTS units it's the Device Role field in each member's mdadm superblock, which mdadm --examine prints. On QuTS hero & TrueNAS it's the ZFS vdev label on each disk.

We image each member on PC-3000 Portable III or DeepSpar Disk Imager hardware, then assemble the array in software from the clones. An SHR volume assembles with mdadm --assemble --readonly, its LVM volume group activates, & its Btrfs or ext4 filesystem mounts read-only on an unpatched upstream kernel, because Synology adds no incompatible-feature flag to its Btrfs. RAID F1 on FlashStation units is the exception: it uses Synology-private md layout numbers that mainline Linux doesn't implement, so upstream mdadm won't assemble it.

Unraid doesn't stripe data. Each data disk holds its own XFS, Btrfs, or ZFS filesystem, backed by one or two dedicated parity disks, & any healthy data disk mounts by itself on a Linux workstation. WD My Cloud NAS members are mdadm & ext4 with no bridge-chip encryption, so they read as plaintext unless software volume encryption was turned on; the My Book & My Passport USB enclosures encrypt in the bridge instead.

Drobo arrays are different again. BeyondRAID is proprietary, closed-source block virtualization whose Data Allocation Table lives on the disks, so the chassis can stay home, but the clones go through BeyondRAID-aware parsing software. Drobo's parent company, StorCentric, filed for Chapter 7 in 2023, & Drobo support ended on January 27, 2023.

Don't move the drives into a replacement NAS & click Migrate or Repair after a metadata crash. That works after a dead power supply. After an interrupted mdadm sync or a damaged Btrfs tree root, those options rewrite the system partitions & force the arrays to import; the import frequently fails, & the next offer is a fresh install that permanently overwrites the remaining data partitions.

An encrypted volume still needs its key or key file to travel with the drives.

How it works

All NAS recovery is performed in-house at our single Austin, TX lab. We accept mail-in shipments from all 50 states with no outsourcing. We work in six steps, and we image first: a free evaluation, then we image every member, capture the metadata, reconstruct the array offline, pull the files, and deliver data we've verified. No diagnostic fees. No data, no recovery fee. See per-member pricing.

Pricing

How Much Does NAS Data Recovery Cost?

NAS recovery uses per-member imaging fees plus a $400-$800 array reconstruction fee billed separately. Logical and firmware imaging uses standard HDD tier pricing; head swap mechanical work uses higher tiers. A 4-bay array means four imaging fees plus one reconstruction fee. No data recovered means no charge.

NAS recovery uses a two-tiered pricing model: a per-member imaging fee for each individual drive in the array, plus a final array reconstruction fee of $400-$800. For example, a 4-bay NAS means four separate imaging fees plus the reconstruction fee. If we cannot recover your data, there is no charge.

Service TierPrice Range (Per Drive)Description
Logical / Firmware Imaging$250-$900Filesystem corruption and firmware module damage requiring PC-3000 terminal access.
Mechanical (Head Swap / Motor)$1,200-$1,50050% depositAir-filled donor parts consumed during transplant. Helium-sealed NAS drives use $3,000–$4,500 head swap or $4,000–$5,000 surface damage pricing plus helium and donor costs.
Array Reconstruction$400-$800per arrayDepends on RAID level, member count, filesystem type (Btrfs, EXT4, XFS, ZFS), and whether parameters must be detected from raw data. Data Extractor Express RAID Edition, the ACE Lab RAID/array software that runs on the PC-3000, performs parameter detection and virtual assembly from cloned images.

No Data = No Charge: If we recover nothing from your NAS, you owe $0. Free evaluation, no obligation.

We are not HIPAA certified and do not sign BAAs.

Per-Drive Pricing Reference

Each NAS member drive is priced individually based on the type of failure. Air-filled NAS drives use the standard HDD tiers. Helium-sealed enterprise NAS drives use the helium HDD tiers for firmware and mechanical work. Array reconstruction ($400-$800) is billed separately after all members are imaged. Every member bills as its own imaging line item, which the per-drive NAS recovery cost breakdown walks through tier by tier alongside the separate reconstruction fee.

Air-filled NAS member pricing

  1. Low complexity

    Simple Copy

    Your drive works, you just need the data moved off it

    Functional drive; data transfer to new media

    Rush available: +$100

    $100

    3-5 business days

  2. Low complexity

    File System Recovery

    Your drive isn't recognized by your computer, but it's not making unusual sounds

    File system corruption. Accessible with professional recovery software but not by the OS

    Starting price; final depends on complexity

    From $250

    2-4 weeks

  3. Medium complexity

    Firmware Repair

    Your drive is completely inaccessible. It may be detected but shows the wrong size or won't respond

    Firmware corruption: ROM, modules, or translator tables corrupted; requires PC-3000 terminal access

    CMR drive: $600. SMR drive: $900.

    $600–$900

    3-6 weeks

  4. High complexity

    Head Swap

    Bench diagnosis found the read/write heads have to be replaced. Clicking can also come from firmware, the preamp, or the spindle

    Head stack assembly failure. Transplanting heads from a matching donor drive on a clean bench

    50% deposit required. CMR: $1,200-$1,500 + donor. SMR: $1,500 + donor.

    50% deposit required

    $1,200–$1,500

    4-8 weeks

  5. High complexity

    Surface / Platter Damage

    Your drive was dropped, has visible damage, or a head crash scraped the platters

    Platter scoring or contamination. Requires platter cleaning and head swap

    50% deposit required. Donor parts are consumed in the repair. Most difficult recovery type.

    50% deposit required

    $2,000

    4-8 weeks

Hardware Repair vs. Software Locks

Our "no data, no fee" policy applies to hardware recovery. We do not bill for unsuccessful physical repairs. If we replace a hard drive read/write head assembly or repair a liquid-damaged logic board to a bootable state, the hardware repair is complete and standard rates apply. If data remains inaccessible due to user-configured software locks, a forgotten passcode, or a remote wipe command, the physical repair is still billable. We cannot bypass user encryption or activation locks.

No data, no fee. Free evaluation and firm quote before any paid work. Full guarantee details. Head swap and surface damage require a 50% deposit because donor parts are consumed in the attempt.

Rush fee
+$100 rush fee to move to the front of the queue
Donor drives
Donor drives are matching drives used for parts. Typical donor cost: $50–$150 for common drives, $200–$400 for rare or high-capacity models. We source the cheapest compatible donor available.
Target drive
The destination drive we copy recovered data onto. You can supply your own, or we'll provide one. For larger capacities (8TB, 10TB, 16TB and above), target drives cost $400+ extra. All prices are plus applicable tax.

Sealed helium drives are on their own price list, $200–$5,000+. When a head swap or platter repair opens one, we refill it with helium. That adds $400–$800, and the donor has to be an exact match. Helium drive prices

Helium-sealed NAS member pricing

  1. Low complexity

    Simple Copy

    Your helium drive works, you just need the data moved off it

    Functional drive; data transfer to new media

    Rush available: +$100

    $200

    3-5 business days

  2. Low complexity

    File System Recovery

    Your helium drive isn't recognized by your computer, but it's not making unusual sounds

    File system corruption. Accessible with professional recovery software but not by the OS

    Starting price; final depends on complexity

    From $600

    2-4 weeks

  3. Medium complexity

    Most Common

    Firmware Repair

    Your helium drive is completely inaccessible. It may be detected but shows the wrong size or won't respond

    Firmware corruption: ROM, modules, or translator tables corrupted; requires PC-3000 terminal access

    $900–$1,200

    3-6 weeks

  4. High complexity

    Head Swap

    Bench diagnosis found the read/write heads have to be replaced. Clicking can also come from firmware, the preamp, or the spindle

    Head stack assembly failure. Transplanting heads from a matching helium donor drive on a clean bench. Helium refill required.

    50% deposit required. Helium cost ($400-$800) and donor drive cost additional.

    50% deposit required

    $3,000–$4,500

    4-8 weeks

  5. High complexity

    Surface / Platter Damage

    Your helium drive was dropped, has visible damage, or a head crash scraped the platters

    Platter scoring or contamination. Requires platter cleaning, head swap, and helium refill

    50% deposit required. Helium cost ($400-$800) and donor drive cost additional. Most difficult recovery type.

    50% deposit required

    $4,000–$5,000

    4-8 weeks

Hardware Repair vs. Software Locks

Our "no data, no fee" policy applies to hardware recovery. We do not bill for unsuccessful physical repairs. If we replace a hard drive read/write head assembly or repair a liquid-damaged logic board to a bootable state, the hardware repair is complete and standard rates apply. If data remains inaccessible due to user-configured software locks, a forgotten passcode, or a remote wipe command, the physical repair is still billable. We cannot bypass user encryption or activation locks.

No data, no fee. Free evaluation and firm quote before any paid work. Full guarantee details. Head swap and surface damage require a 50% deposit because donor parts and helium are consumed in the attempt.

Rush fee
+$100 rush fee to move to the front of the queue
Helium cost
Helium cost: $400-$800 additional for head swap and surface damage tiers. This covers the helium refill required after opening the sealed chamber.
Donor drives
Helium donor drives must be an exact match. Typical donor cost: $200–$600 depending on model and availability, plus helium refill cost ($400–$800) required after opening the sealed chamber.
Target drive
The destination drive we copy recovered data onto. You can supply your own or we provide one at cost plus a small markup. For larger capacities (8TB, 10TB, 16TB and above), target drives cost $400+ extra. All prices are plus applicable tax.
Overview

What Is NAS Data Recovery and When Is It Needed?

We get the files off a failed Synology, QNAP, or Buffalo array by imaging each member drive on PC-3000 or DeepSpar hardware, then reconstructing the RAID array and filesystem metadata offline from the clones.

NAS data recovery is the process of extracting files from a failed or degraded network-attached storage device by imaging each member drive independently and reconstructing the RAID array, filesystem metadata, and shared folder structures offline from the clones.

  • NAS devices from Synology, QNAP, and Buffalo run Linux software RAID (mdadm) or ZFS under their own management layers. When the storage pool degrades or the volume crashes, the vendor's web interface often offers only destructive options: reinitialize, recreate, or force-repair.
  • Common triggers include a second member drive failing during a rebuild, firmware updates that corrupt RAID metadata, and accidental LUN or volume deletion.
  • To recover it, we image each member on PC-3000 or DeepSpar hardware, detect the RAID parameters (stripe size, parity rotation, member order), and reassemble the array virtually from the cloned images.
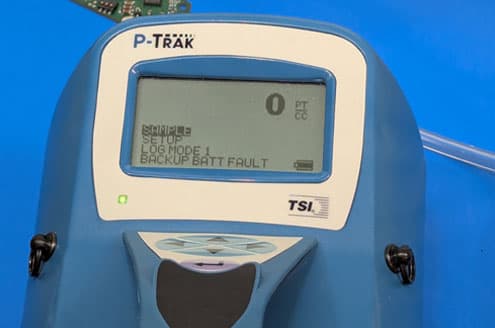
Particle counter display showing a reading of zero
A particle counter reading 0 particles per cubic centimeter.
Symptoms

What Symptoms Indicate a NAS Needs Professional Recovery?

NAS failure symptoms include "Volume Crashed," "Storage Pool Degraded," inaccessible shared folders, and stuck rebuilds. Every symptom calls for the same response: stop all write activity and power down the NAS. A forced rebuild's sustained reads can push a failing member into mechanical failure.

NAS failure symptoms range from "Volume Crashed" and "Storage Pool Degraded" warnings to inaccessible shared folders and stuck rebuilds. The correct response to every symptom is the same: stop all write activity, power down the NAS, and avoid forced rebuilds or reinitialization.

  • Volume crashed / Storage pool degraded: Don't force a rebuild on failing members. Its sustained reads can push a marginal drive into failure. Power down and stop writes.
  • Cannot access shared folders: Don't accept prompts to repair or recreate. Initialization overwrites critical RAID metadata.
  • Multiple disk errors in logs: Avoid swapping drive order or hot-plugging repeatedly. Label drives and preserve original slot assignments.
  • Drives showing as offline: Don't keep power-cycling.
  • RAID rebuilding stuck: Power down immediately.
  • Encrypted volumes inaccessible: Have encryption keys and passwords available. We keep data offline and under chain-of-custody.

Volume crashed / Storage pool degraded

Do not force a rebuild on failing members; its sustained reads can push a marginal drive into failure. Power down and stop writes.

Cannot access shared folders

Do not accept prompts to repair/recreate. Initialization overwrites critical metadata.

Multiple disk errors in logs

Avoid swapping order or hot-plugging repeatedly. Label drives and preserve original order.

Drives showing as offline

Do not keep power-cycling.

RAID rebuilding stuck

Power down immediately.

Encrypted volumes inaccessible

Have keys/passwords available. We keep data offline and under chain-of-custody during work.

If your NAS uses ZFS and zpool import is failing with I/O errors, see our ZFS pool import I/O error recovery guide. For Synology-specific "Volume Crashed" diagnostics, see the Synology volume crash recovery guide.

If a rebuild was already attempted on weakening members, read about how forced NAS RAID rebuilds cause permanent data loss. For NAS units reporting a degraded storage pool, we image each member before any reconstruction.

Important: Any write activity (rebuilds, "repairs", new shares) can overwrite recoverable data. Power down and contact us.

Why SSH-Based Recovery Software Endangers Degraded NAS Drives

SSH-based NAS recovery software reads every member through the NAS operating system, and it has no per-head control over how a failing drive gets read. When the heads are degrading, those sustained reads push a marginal drive toward mechanical failure.

A hardware imager like the DeepSpar Disk Imager handles each head differently depending on how degraded that head is, and it runs customizable read algorithms.

SSH-based software has none of these controls.

If your NAS has mechanical symptoms (clicking, intermittent disconnects, slow access on specific shares), power it down. Don't turn on SSH recovery utilities. The drives have to come out, go onto imaging hardware, and get cloned sector-by-sector before anyone attempts a reconstruction.

Process

How Do We Recover Data from a Failed NAS?

We do NAS data recovery in six steps, and imaging comes first. We document the configuration, clone each member on PC-3000 or DeepSpar hardware, capture the RAID metadata, reconstruct the array offline from the clones, extract the files, and deliver verified data.

We recover NAS arrays using a six-step image-first workflow: document the configuration, clone each member on PC-3000 or DeepSpar imaging hardware, capture RAID metadata, reconstruct the array offline from images, extract files, and deliver verified data.

  1. Free evaluation and diagnostic: Document NAS model, RAID level (SHR, RAID 5, RAID 6, etc.), member count, encryption status, and any prior rebuild or repair attempts. No experiments run on original drives.
  2. Forensic imaging: Clone each member drive using PC-3000 and DeepSpar hardware. Donor part transplants are performed for members with mechanical failures before imaging begins.
  3. Metadata capture: Copy RAID headers and superblocks. Record stripe sizes, parity rotation, member offsets, and filesystem type (Btrfs, EXT4, XFS, ZFS).
  4. Offline array reconstruction: Assemble the virtual array from cloned images only. Validate parity consistency and filesystem integrity across the reconstructed volume.
  5. Filesystem extraction and recovery: Rebuild or correct the filesystem on the clone, carve fragmented files where needed, and verify priority data such as shared folders, virtual machines, and databases.
  6. Delivery: We copy the recovered data to your target media and check file integrity with you.
Typical timing: each drive gets the turnaround for its own pricing tier: 2-4 weeks for file system recovery, 3-6 weeks for firmware repair, and 4-8 weeks for a head swap.
Consumer vs enterprise

Consumer NAS vs. Enterprise NAS: How Drive Architecture Affects Recovery

Recovery complexity depends on the drive architecture inside the NAS chassis. If an SMR member's translator is damaged, it needs firmware work before we can image it. If a helium-sealed member needs mechanical work, we refill it with helium after we open the sealed chamber. Helium adds $400–$800 per member for head swap and surface damage work.

Recovery complexity depends on the hard drive architecture inside the NAS chassis. Consumer-grade NAS arrays populated with SMR drives and enterprise arrays using helium-sealed drives present different mechanical and firmware challenges during imaging.

Consumer NAS Arrays and SMR Drive Complications

SMR overlaps data tracks to increase capacity. On Western Digital drive-managed SMR drives, a second-level translator keeps track of where those writes landed.

When that translator is damaged, the drive reads zeros in every sector. We have to repair the firmware problem before sector imaging returns user data. This adds a firmware repair step to every affected member in the array.

Enterprise NAS and Helium-Sealed Drive Recovery

We handle helium-sealed drives in-house, including the mechanical work, the helium refill, and platter cleaning.

CMR vs SMR

CMR vs SMR Drives for NAS: Which Belongs in an Array?

Put CMR drives in a NAS array, not SMR. CMR (Conventional Magnetic Recording) writes tracks side by side, so a RAID rebuild runs at a steady write speed. Device-managed SMR (Shingled Magnetic Recording) drives stall for 30 to 60 seconds once their internal cache fills, & the array reads a mechanically healthy drive as dead & ejects it.

CMR drives belong in a NAS array; device-managed SMR drives do not. The difference is how the platter is physically written, & it decides whether a rebuild finishes or whether a healthy drive gets kicked out of the array partway through.

How CMR and SMR Write the Platter Differently

CMR lays each magnetic track down side by side with a guard gap between tracks, so the drive can overwrite any single track in place without disturbing its neighbors.

SMR overlaps the tracks like roof shingles to pack more data onto the same platter. The overlap is what creates the problem: you can no longer rewrite one track without re-writing the shingled band of tracks stacked on top of it.

To hide that penalty, an SMR drive keeps a small CMR cache zone, a strip of non-overlapping tracks where incoming writes land first, then drains those writes into the shingled area during idle time.

The WD Red SMR drives are device-managed (DM-SMR), meaning the drive handles all of this internally & presents itself to your NAS as an ordinary hard drive.

Why Do SMR Drives Drop Out of a NAS Rebuild?

A DM-SMR drive gets ejected mid-rebuild because the rebuild never gives it idle time to empty its cache. A RAID rebuild or ZFS resilver is a sustained, hours-long stream of writes.

The CMR cache zone fills, & with no idle window to drain it, the drive is forced into aggressive shingle-band rewrites while writes keep arriving. Those rewrites push command latency to 30 to 60 seconds, well past the Linux kernel & RAID controller command timeout.

The array interprets a timeout from a mechanically healthy drive as a dead member & drops it, which can collapse a single-drive failure into a degraded or failed array.

The drive that just got kicked out is usually fine. The platters, heads, & motor are healthy, & the firmware just couldn't answer in time. A clicking head-crash drive fails the opposite way. That's why we image every member with imaging hardware (a DeepSpar Disk Imager, or a PC-3000 Portable III or Express) before any array reassembly. We don't force the live NAS to rebuild onto a drive that keeps timing out.

RAID is not a backup. A NAS array keeps you running with no downtime when a single drive dies. It does nothing for a second drive failing during the rebuild, a ransomware run, an accidental delete, or a controller failure. The drive architecture you pick changes how likely that rebuild is to survive, but it never turns the array into a backup copy.

CMR vs SMR for NAS: Side-by-Side Comparison

PropertyCMR (Conventional)DM-SMR (Device-Managed Shingled)
Track layoutSide by side, non-overlapping, in-place rewriteOverlapping like roof shingles; bands rewritten together
Sustained-write behaviorSteady; no hidden cache to exhaustCMR cache zone fills, then stalls 30 to 60 seconds
RAID rebuild / ZFS resilverSteady write speed through the rebuildLatency stalls exceed the controller timeout; drive ejected
WD Red identifiersWD Red PlusPlain WD Red 2/3/4/6TB (e.g. WD40EFAX, WD60EFAX)
Firmware-repair recovery, per member$600$900
Head-swap recovery, per member$1,200–$1,500$1,500

The recovery-cost rows reflect the extra firmware work an SMR translator demands. SMR (Shingled Magnetic Recording) drives require more work at the firmware and head-swap tiers due to their overlapping track architecture. Both figures are per evaluated member, billed individually for each drive that needs the work; a free evaluation comes first, & if we recover nothing you owe $0.

CMR (Conventional Magnetic Recording)
Data tracks sit side by side without overlapping, so any track can be overwritten in place. Write speed stays steady through a RAID rebuild.
SMR (Shingled Magnetic Recording)
Data tracks overlap like roof shingles to raise density. Rewrites force whole shingled bands to be re-written through a small CMR cache zone; once that cache fills under sustained writes, the drive stalls long enough for a NAS to time it out & eject it.

What to Check Before You Build or Rebuild an Array

Check the exact model number before you trust a drive in an array, because the WD Red label alone doesn't tell you whether a drive is CMR or SMR. The plain WD Red drives in 2TB, 3TB, 4TB, & 6TB capacities are DM-SMR (WD20EFAX, WD30EFAX, WD40EFAX, & WD60EFAX).

WD Red Plus is CMR at every capacity in the line.

If an SMR drive has already dropped out & corrupted its translator, don't force the NAS to assemble or rebuild onto it. Forcing the assembly marks failed members as working so the array can start. The mdadm manual warns that an array that needs --force may contain data corruption.

Power the NAS down & leave the drives alone. We image that member first, using the same WD firmware workflow we use to rebuild a corrupted translator before sector imaging begins.

WD My Cloud

WD My Cloud Data Recovery: What the Linux Layout Means for Your Files

WD My Cloud NAS units run embedded Linux on mdadm software RAID with an ext4 filesystem & no bridge-chip encryption. Unless you turned on software volume encryption, the data is plaintext & mounts directly in a Linux recovery rig. Single-drive My Book & My Passport USB enclosures & the My Cloud Home are the opposite case.

The WD My Cloud name covers several products that store data in completely different ways. Knowing which one you have decides whether the data is plaintext ext4 you can read on a Linux box or ciphertext locked behind a bridge chip.

Multi-Bay My Cloud NAS Units Run mdadm and ext4

The multi-bay My Cloud enclosures run an embedded Linux operating system that stores your shares on mdadm software RAID with an ext4 filesystem on top. They don't encrypt the platter through a bridge chip.

Unless you explicitly turned on software volume encryption in the dashboard, the data is plaintext ext4 that mounts directly in a Linux recovery rig once each disk is imaged.

That doesn't mean you should pull the disks & drop them into a new enclosure. The array geometry lives in the mdadm metadata on the disks, & a different enclosure or a forced rebuild can overwrite that metadata & the partition layout before you ever see your files. We image every disk first on PC-3000 or DeepSpar hardware, then assemble the array read-only from the clones with mdadm.

See the WD My Cloud recovery page for the model-by-model breakdown.

My Book and My Passport USB: Bridge-Chip AES, Shucking Yields Ciphertext

Single-drive WD My Book & My Passport USB enclosures are the opposite of a My Cloud. Many of them route the drive through a USB-to-SATA bridge chip (JMicron & Symwave families are common) that encrypts the platter with AES, even when you never set a password.

If you shuck the drive, remove it from the enclosure & connect it straight to a desktop, you get ciphertext, not your files.

Shucked drives have a second trap, even when encryption isn't involved. A drive with the optional SATA 3.3 Power Disable feature treats pin 3 of the SATA power connector as a power-disable pin. It won't power up on a power supply that drives 3.3V on pin 3.

Our Western Digital recovery workflow handles the bridge & the power-disable pin together.

My Cloud Home: Content IDs and an index.db, Not a Normal Share

The My Cloud Home is its own case & catches people who expect a normal My Cloud. It renames every file you upload to a 64-character hexadecimal content ID on disk. Your real filenames, folders, & the mapping back to those content IDs live in a SQLite database (index.db).

Image the disk & you find a directory full of hex-named blobs that look like garbage until index.db is parsed to reattach the original names. We pull the content IDs & reconcile them against index.db so files come back with their real names & folder structure intact.

A single-bay My Cloud Home holds one SATA drive with no RAID underneath, so it clones at the sector level like any other single drive. Our My Cloud Home index.db rebuild starts from that clone and ends with the SQLite mapping reattached to the blobs.

Ransomware

NAS Ransomware Recovery: Deadbolt, QLocker, and eCh0raix

Deadbolt, QLocker, and eCh0raix ransomware hit Internet-exposed QNAP and Synology devices. The underlying RAID geometry usually stays intact. We start by imaging every member. Then we look for Btrfs or ZFS snapshots taken before the attack and pull the files they hold off the clones, and nobody pays the ransom.

NAS-specific ransomware (Deadbolt, QLocker, eCh0raix) targets Internet-exposed Synology and QNAP devices by locking shared folder files. The underlying RAID geometry usually remains intact, and recovery focuses on filesystem-level forensic extraction from cloned member images rather than paying the ransom.

QNAP tied QLocker to vulnerabilities it had patched in QTS and in Multimedia Console. Unit 42 found an eCh0raix variant delivered to QNAP devices through CVE-2021-28799. Deadbolt encrypted files on QNAP devices with AES-128 and replaced the QNAP login page with its ransom screen. QLocker moved files into password-protected 7-Zip archives.

eCh0raix targeted both Synology and QNAP devices.

  1. Power down the NAS. We image every member at intake.
  2. We clone each member on PC-3000 or DeepSpar hardware.
  3. We look for Btrfs or ZFS snapshots taken before the attack and extract the files they hold from the clones.

For broader ransomware recovery scenarios beyond NAS devices, see our ransomware data recovery service.

Buffalo TeraStation

How Do You Recover a Buffalo TeraStation Stuck in Emergency Mode?

Buffalo TeraStation and LinkStation units enter Emergency Mode when the firmware boot partition on the member drives corrupts. NASNavigator then reports the array as Unformatted even though user data on the mdadm volume is usually intact. We image each drive, reassemble the mdadm array from the clones, and read the XFS log offline with xfs_logprint before any repair tool touches the metadata.

Buffalo TeraStation's Emergency Mode is usually a firmware boot failure rather than a data failure. The recovery path is offline reassembly of the mdadm array from cloned members, followed by read-only XFS extraction with xfs_db and xfs_logprint. Running xfs_repair -L on the original drives can lose user files.

Buffalo network appliances run standard Linux mdadm. The data volume is predominantly XFS, with ext4 on some units. When firmware corruption hits the boot partition on the member drives, the TeraStation drops into Emergency Mode.

NASNavigator then shows the device as Unformatted, even though the user data is usually still intact.

If you pull the drives, assemble the array on a workstation with mdadm --assemble, and then run xfs_repair -L on the assembled volume, you zero the XFS log, even if it's dirty.

The xfs_repair manual says that loses every metadata update that was in progress at the time of the crash, which may cause significant filesystem damage. It also says zeroing the log should only be a last resort. A Buffalo TeraStation in Emergency Mode hasn't reached that point.

On a Buffalo TeraStation we image every member through imaging hardware (PC-3000 Portable III or DeepSpar Disk Imager). We assemble the cloned set with mdadm --assemble --readonly so nothing writes to the assembled array. Then we look at the XFS state with xfs_logprint before deciding whether the log can be replayed cleanly.

When the log is intact we mount the assembled image read-only and copy files out. When the log holds incomplete transactions we read the B+tree directly with xfs_db in read-only mode, walking inode chunks and directory blocks by hand to extract files without ever writing back to the clone. Either way, the original member drives sit on the shelf untouched, so a second attempt is always possible if the first pass missed a directory subtree.

Emergency Mode
The firmware state a Buffalo TeraStation or LinkStation enters when firmware corruption hits the boot partition on its member drives. NASNavigator reports the unit as Unformatted. Emergency Mode is a boot failure, not a data failure: the XFS user volume on the member drives is usually intact.
xfs_logprint
The XFS utility that prints the log of an XFS filesystem. We run it against the assembled mdadm image to determine whether the log holds complete transactions (safe to replay) or partial transactions (require direct B+tree extraction with xfs_db).

Don't run: xfs_repair -L, mdadm --create on the original drives. Each one writes to the array. Power down the unit, pull the drives in labelled slot order, and have every member imaged before any repair attempt.

Filesystem recovery

Which NAS Filesystems and RAID Modes Do We Support?

We recover data from Btrfs, EXT4, XFS, and ZFS filesystems across Synology SHR and SHR-2, standard RAID 0, 1, 5, 6, and 10, and QNAP QuTS hero ZFS pools. Each filesystem needs its own metadata parsing.

We recover data from Btrfs, EXT4, XFS, and ZFS filesystems across Synology SHR/SHR-2, standard RAID 0/1/5/6/10, and QNAP QuTS hero ZFS pools. Each filesystem requires different metadata parsing and reconstruction techniques.

Synology SHR / SHR-2
Synology Hybrid RAID uses mdadm with variable-size partitions to mix drive capacities. SHR-2 adds dual parity equivalent to RAID 6. We parse the custom partition layout and mdadm superblocks from each member image.
Btrfs on NAS
Btrfs stores metadata in a tree structure across members. We reconstruct the chunk tree and device tree from imaged copies to locate and extract files.
ZFS (QNAP QuTS hero)
QNAP's QuTS hero uses ZFS. We clone the members and attempt a read-only pool import. If the newest pool state is damaged, zpool import's recovery mode can return the pool to an importable state by discarding the last few transactions. See our ZFS pool recovery guide. QuTS hero units running native ZFS rather than the QTS md and LVM stack are handled under QNAP QuTS hero ZFS pool recovery.
EXT4
QNAP QTS, WD My Cloud NAS units, and legacy ReadyNAS OS4/OS5 units store their data on ext4, and Synology offers it as a volume option. EXT4 journal recovery and inode reconstruction from degraded arrays is a standard part of our workflow.
XFS
Most Buffalo TeraStation and LinkStation units store their data on XFS. XFS allocation group headers and B+ tree metadata are reconstructed from member images during recovery.
Encrypted Volumes
Recovery of encrypted volumes requires the original encryption key or passphrase. Without it, the data cannot be decrypted regardless of array condition.

Advanced Offline Reconstruction Mechanics

Once each member is imaged and the RAID layer is virtually reassembled from clones, filesystem-level damage determines the reconstruction approach. Each filesystem stores metadata differently, and the wrong repair command on the wrong filesystem type will overwrite the structures needed for recovery. EXT4 journal replay, Btrfs chunk tree reconstruction, and ZFS Uberblock rollback are each handled from cloned images.

Once each member is imaged and the RAID layer is virtually reassembled from clones, the filesystem-level damage determines the reconstruction approach. Each filesystem stores metadata differently, and the wrong repair command on the wrong filesystem type will overwrite the structures needed for recovery.

  • EXT4 journal replay: When an EXT4-based NAS (such as WD My Cloud NAS units) crashes mid-write, we can replay its jbd2 journal up to the latest commit record. We replay the committed transactions from the cloned array image to restore inode consistency and reconstruct orphaned directory entries on the clone.
  • Btrfs chunk tree and subvolume reconstruction: Btrfs uses a chunk tree to convert its logical addresses to physical addresses on the underlying device. We extract from the clones with read-only tools such as btrfs-find-root and btrfs restore.
  • ZFS Uberblock rollback: On QNAP QuTS hero devices, each ZFS vdev label ends in an array of uberblocks that is updated as transaction groups commit. When the newest state points at damaged metadata (causing pool import I/O errors), zpool import's recovery mode can discard the last few transactions to get the pool importable again. We run it against the clones.

iSCSI LUN and Virtual Machine Recovery on NAS Storage

Enterprise Synology and QNAP deployments host iSCSI targets for VMware ESXi, Proxmox, and Hyper-V. When the NAS fails, iSCSI LUNs are raw block devices containing their own internal filesystems (such as VMFS or NTFS), not partitions of the NAS filesystem. Recovery is two-stage: reconstruct the NAS filesystem from clones, then parse the raw LUN images.

Enterprise Synology and QNAP deployments host iSCSI targets for VMware ESXi, Proxmox, and Hyper-V hypervisors. When the NAS fails, iSCSI LUNs are not visible as standard shared folders. On Synology, a file-level LUN is a file on the underlying Btrfs or ext4 volume, under the hidden @iSCSI directory. Recovery requires a two-stage logical extraction.

  1. Reconstruct the underlying NAS filesystem (Btrfs, EXT4, or ZFS) from cloned member images to locate the files representing each LUN.
  2. Parse the filesystem the host put inside each LUN image, such as VMFS on an ESXi host or NTFS on a Windows host. We extract .vmdk, .vhdx, and flat image files directly from the reconstructed block layer without relying on the NAS operating system to mount damaged LUNs.

For NAS arrays where an iSCSI LUN was accidentally deleted, we scan unallocated space on the member images for orphaned file headers. For virtual machine recovery from server environments, the same LUN extraction workflow applies whether the host was a dedicated server or a NAS acting as a SAN target.

mdadm, LVM, and ZFS Configuration Recovery Parameters

NAS arrays store their geometry in on-disk metadata that must be parsed before any filesystem can be mounted. We detect these parameters from cloned images rather than trusting the NAS operating system, which protects against cases where the vendor configuration database has desynced from the actual array state, including mdadm superblock versions, LVM physical volume headers, and ZFS vdev labels.

NAS arrays store their geometry in on-disk metadata that must be parsed before any filesystem can be mounted. We detect these parameters from cloned images rather than trusting the NAS operating system, which protects against cases where the vendor configuration database has desynced from the actual array state.

mdadm Superblock Versions and Safe Commands

Linux mdadm stores RAID parameters in a superblock whose position depends on its version. Per md(4), version 0.90 is written into a 64K-aligned block that starts at least 64K and less than 128K from the end of the device. Version 1.0 sits between 8K and 12K from the end, on a 4K boundary.

Version 1.1 sits at the start of the device. Version 1.2, the modern default, sits 4K from the start.

When superblocks are intact, we read them with mdadm --examine /dev/sdX to print the metadata stored on each device. For virtual assembly we use mdadm --assemble --readonly to start the array read only. We never use mdadm --create on a recovery target because it writes new metadata to each device and starts a resync. When superblocks are missing, we scan for filesystem magic bytes to determine the data offset and reconstruct the geometry virtually.

LVM Physical Volume and Volume Group Metadata

QNAP QTS and Synology SHR both layer LVM above mdadm. By default the LVM2 label sits in the second sector of each physical volume. When LVM metadata is damaged, we parse the raw PV headers on the clones to rebuild the VG layout.

ZFS Vdev Labels, Uberblocks, and DDT RAM Requirements

ZFS writes four copies of the vdev label on each disk, two at the start and two at the end.

The second half of each label is an array of uberblocks, updated whenever a transaction group commits. We read the vdev labels directly from cloned members to reconstruct the pool topology, then look for the newest intact uberblock.

ZFS deduplication creates a Deduplication Table, and holding it in ARC takes roughly 1 to 5 GB of RAM per 1 TB of deduplicated data. The DDT is stored on disk and read on demand, so a pool whose DDT doesn't fit in RAM still imports. iXsystems says loading the table on demand can take days after an import or reboot. That's a RAM-sizing problem, and the platters aren't at fault. Reading existing data doesn't need the DDT.

So for recovery we import the pool read-only. Running zdb -lu /dev/sdX against a member's block device prints that device's vdev labels and uberblocks. If the SLOG device fails after a sudden power loss, the synchronous writes that were in flight are gone for good. That loss has nothing to do with the pool structure, and nobody can get those writes back from the main vdevs.

For a pool that won't mount, we walk through the read-only import step by step in TrueNAS zpool import recovery.

How We Handle Encrypted NAS Arrays

We clone every member, reconstruct the RAID and LVM layers offline, then decrypt using the client-provided key. If the key is lost, the data can't be recovered.

  1. Clone every member drive. Our recovery process for encrypted NAS volumes follows the same imaging-first workflow.
  2. Reconstruct the RAID and LVM layers offline from the cloned images and assemble the encrypted volume.
  3. Decrypt with the encryption key, passphrase, or exported key file you give us. If the key is lost, the data stays encrypted, and no lab can recover it, ours included.
Why us

Why Choose Rossmann Group for NAS Recovery?

We image NAS member drives on PC-3000 and DeepSpar hardware at our single lab in Austin, and there's no evaluation fee. Transparent pricing is published per tier. If no usable data is recovered, you owe $0.

Rossmann Group uses PC-3000 and DeepSpar imaging hardware in a single Austin lab with no evaluation fees. If we can't recover usable data, you owe $0.

Image-first, offline reconstruction

We never rebuild risky arrays in place. Everything is assembled from clones for safety.

Imaging hardware

PC-3000 and DeepSpar imaging.

Transparent pricing

Clear ranges by member count and condition.

No evaluation fees

Free estimate and honest likelihood of success before paid work begins.

No data, no charge

If we cannot recover usable data, you owe $0 (optional return shipping).

Enterprise

NAS Recovery for IT Administrators, MSPs, and In-House IT Teams

Business NAS arrays carry production databases, client deliverables, and operational records that cannot be reconstructed from other sources.

Compliance Certifications

We aren't HIPAA certified, & we don't sign Business Associate Agreements.

We aren't SOC 2, ISO 27001, FedRAMP, or FERPA certified either. The controls we do have are documented on our data security page. If your compliance requirements mandate any of those certifications, use a lab that holds them.

Multi-Array Pricing

Per-array pricing follows the published per-member tiers and the $400-$800 array reconstruction fee documented in the pricing table above. RAID geometry sets the minimum member count, so RAID level effects on NAS recovery pricing maps each layout to the drives it puts on the invoice.

For enterprise rackmount arrays specifically (Synology RackStation, QNAP enterprise series, and full server platforms), the per-member logical work is identical to consumer arrays, but helium-sealed mechanical work uses helium HDD pricing. Helium cost: $400-$800 additional for head swap and surface damage tiers. This covers the helium refill required after opening the sealed chamber. TrueNAS and FreeNAS rackmount units running OpenZFS pools are covered under TrueNAS server data recovery.

Expedited Turnaround

A $100 rush fee moves your work to the front of the queue.

Rush priority doesn't shorten mechanical work or donor sourcing, because head swaps and donor matching have physical lead times.

Engagement Inquiry

Email help@rossmanngroup.com or call (512) 212-9111 with the array list, RAID level, member count, drive models if known, and any prior rebuild or repair attempts.

There's no diagnostic fee. The evaluation is free. For RAID-only engagements where the array is built directly on a server controller (not a NAS appliance), the same intake workflow applies.

Video

Lab Data Recovery by Rossmann Repair Group

NAS brands

NAS Recovery by Manufacturer

We recover data from Synology, QNAP, Buffalo, ASUSTOR, Unraid, TerraMaster, WD My Cloud, Netgear ReadyNAS, and Drobo devices. Each uses a different storage stack. QNAP QuTS hero relies on native ZFS, while QNAP QTS layers mdadm under LVM under EXT4. Synology SHR uses mdadm with variable partitions under LVM and Btrfs or ext4.

We recover data from Synology, QNAP, Buffalo, ASUSTOR, Unraid, TerraMaster, WD My Cloud, Netgear ReadyNAS, and Drobo devices. Each manufacturer uses a different storage stack, RAID implementation, and filesystem layer, and we match the recovery workflow to the architecture of the failed device.

QNAP TS-Series and QuTS Storage Architecture

QNAP devices use a multi-layered storage stack that complicates recovery beyond standard RAID reconstruction. A QNAP running QTS uses the Linux md driver for basic RAID redundancy, then wraps the array in LVM (Logical Volume Manager) for volume management. QuTS hero models replace that md and LVM stack with native ZFS.

When a QNAP fails, the built-in QTS/QuTS repair options try an in-place reconstruction that writes to members that are already degraded. We start by pulling the drives and imaging each one on PC-3000 hardware.

From the cloned images, we virtually reassemble the md-raid array, manually parse LVM physical volume headers and logical volume records, and locate the actual filesystem layer (EXT4 on QTS, ZFS on QuTS hero). Only after all metadata layers are verified do we extract files from the reconstructed volume.

Synology Hybrid RAID (SHR) and Btrfs Reconstruction

Synology DiskStation Manager (DSM) uses SHR (Synology Hybrid RAID) to allow mixed-capacity drives in a single storage pool. SHR works by partitioning each drive into multiple segments and creating separate mdadm arrays from matching-size partitions, then combining them under LVM. SHR-2 adds dual parity (functionally equivalent to RAID 6) for two-drive fault tolerance.

This multi-layer partitioning means a Synology with mixed drives may contain several separate mdadm arrays stitched together, each with different member assignments.

Btrfs stores filesystem metadata in B-trees distributed across the underlying block devices. Recovering a Btrfs-on-SHR volume requires reconstructing each mdadm superblock from member images, reassembling the LVM layer, and then parsing the Btrfs chunk tree and device tree to map logical addresses to physical locations on the cloned images.

On Synology volumes formatted EXT4, we do journal-based recovery instead. We reconstruct the EXT4 journal and inode tables from the assembled array image.

We never perform in-place SHR rebuilds on degraded pools. On SHR-1, a second drive failing during the rebuild loses the array. We image first and reconstruct offline from the clones, which avoids that risk.

Enclosure-Level Hardware Risks by Brand

Each NAS brand has distinct enclosure-level risks that affect intake handling and recovery workflow. Understanding these risks before shipping prevents common mistakes such as shucking encrypted drives or initializing corrupted arrays.

Synology NVMe Cache Dropouts
On Synology Plus units, when an NVMe drive acting as a dirty write cache drops off the PCIe bus, its uncommitted writes are permanently lost. The hard drive array is left with an incomplete, corrupted Btrfs filesystem, and DSM reports it as Volume Crashed.
QNAP Partition 1 Corruption
QNAP stores the configuration database that maps storage pools to the mdadm arrays on partition 1 of the member drives. When a failed firmware update corrupts partition 1, the interface reports the pools as empty or uninitialized while the user data on partition 3 is intact. We reconstruct the array directly from the mdadm superblocks and LVM headers on the drive clones.
WD JMicron & Symwave Bridge AES
WD My Book and My Passport USB external drives apply always-on AES in the USB-to-SATA bridge chip (JMicron JMS561, JMS538S, or Symwave SW6316) even when the user never set a password. Shuck the drive and connect it directly to SATA, and you get ciphertext, not data. WD My Cloud NAS units are a different architecture: embedded Linux on mdadm & ext4 with no bridge-chip encryption. Unless the user enabled software volume encryption in the dashboard, the ext4 data is plaintext and a removed drive mounts directly in a Linux recovery rig. My Cloud Home is separate again: it renames every file to a 64-character hex content ID, with the original names and tree held in a proprietary SQLite index.db.
Buffalo's Emergency Mode
Buffalo TeraStation units enter Emergency Mode after firmware corruption on the boot partition. Power down immediately. TeraStation units predominantly use XFS over mdadm, and XFS metadata is sensitive to interrupted writes. That's why we do the replay offline, from the clones.
TerraMaster TOS Boot Corruption
TerraMaster TOS firmware corruption can leave the interface unable to recognize existing arrays, and then it prompts you to initialize the drives. The TRAID metadata (a wrapper around mdadm and LVM) may still be intact on the data partitions, but the initialization prompt is dangerous. We image every member before the NAS writes anything, then reconstruct the mdadm/LVM stack from the clones without trusting the corrupted boot metadata.

Proprietary Filesystem Claims vs Open-Source Reality

Synology DSM, QNAP QTS, TrueNAS, and Asustor ADM all run on documented open-source stacks: Linux mdadm, LVM, Btrfs, ext4, and OpenZFS. These filesystems have public source code.

Recovering them takes forensic parsing of those open-source formats. Proprietary vendor access doesn't come into it.

The same btrfs-find-root, zdb, and mdadm utilities are available to every qualified lab. What separates one lab from another is whether it diagnoses the fault accurately, publishes its prices, and images the drives in-house on PC-3000 and DeepSpar hardware instead of running network scanning tools.

A direct comparison of OpenZFS against controller-based hardware RAID is laid out in ZFS versus hardware RAID.

Recovery by Symptom

Location

Lab Location and Mail-In Service

All NAS recovery work is performed in-house at our single Austin, TX lab at 2410 San Antonio Street, Austin, TX 78705. We accept mail-in shipments from all 50 states with no outsourcing. Drives stay under chain-of-custody from intake through delivery.

All NAS recovery work is performed in-house at our lab: 2410 San Antonio Street, Austin, TX 78705. For clients outside Austin, we accept mail-in shipments from all 50 states. Your drives stay in our lab under chain-of-custody from intake through delivery.

Walk-in evaluations are available Monday - Friday, 10 AM - 6 PM CT. For clients outside Austin, we accept mail-in shipments from all 50 states. Your drives stay in our lab under chain-of-custody from intake through delivery.

Logistics

Shipping

Secure Mail-In from Anywhere in the US

Shipping

Mail-in

Transit time depends on the carrier and service you choose.

Security & Insurance

Fully Insured

Use FedEx Declared Value to cover hardware costs. We return your original drive and recovered data on new media.

Packaging Standards

  • ✓Use the box-in-box method: float a small box inside a larger box with 2 inches of bubble wrap.
  • ✓Wrap the bare drive in an anti-static bag to prevent electrical damage.
  • ✗Do not use packing peanuts. They compress during transit and allow heavy drives to strike the edge of the box.
Chain of custody

How We Handle Your Drives

NAS arrays contain business files, client deliverables, and records that cannot be re-created from other sources. Every drive that enters our lab follows the same custody protocol regardless of array size or data sensitivity.

1

Intake

Every package is opened on camera. Your drive gets a serial number tied to your ticket before we touch anything else.
2

Diagnosis

Chris figures out what's actually wrong: firmware corruption, failed heads, seized motor, or something else. You get a quote based on the problem, not the "value" of your data.
3

Recovery

Firmware work happens on the PC-3000. Head swaps and platter surgery happen in our ULPA-filtered bench. Nothing gets outsourced.
4

Return

Original drive plus recovered data on new media. FedEx insured, signature required.

Data Recovery Standards & Verification

Our Austin lab operates on a transparency-first model. We use industry-standard recovery tools, including PC-3000 and DeepSpar, combined with strict environmental controls to maintain drive integrity. This approach allows us to serve clients nationwide with consistent technical standards.

Transparent History

Serving clients nationwide via mail-in service since 2008. Our lead engineer holds PC-3000 and HEX Akademia certifications for hard drive firmware repair and mechanical recovery.

Media Coverage

Our repair work has been covered by The Wall Street Journal and Business Insider, with CBC News reporting on our pricing transparency. Louis Rossmann has testified in Right to Repair hearings in multiple states and founded the Repair Preservation Group.

Aligned Incentives

Our "No Data, No Charge" policy means we assume the risk of the recovery attempt, not the client.

LR

Technical Oversight

Louis Rossmann

Our engineers review all lab protocols to maintain technical accuracy and honest service. Since 2008, his focus has been on clear technical communication and accurate diagnostics rather than sales-driven explanations.

We believe in showing the bench rather than just describing it. Open-drive work runs on a 0.02 micron ULPA-filtered laminar clean bench, and we filmed it.

See the particle counter test at the bench
FAQ

Common Questions; Real Answers

Can you recover a Synology or QNAP that says "Volume crashed"?
Yes. We image each member on PC-3000 or DeepSpar hardware, capture the RAID metadata, reconstruct the array offline, and recover data from the images. We don't attempt risky in-place repairs or rebuilds on your original NAS.
Should I try a RAID rebuild if it's degraded?
Not if the data is irreplaceable and you don't have a verified backup. A rebuild puts sustained reads on every surviving member, and a marginal one can fail partway through. Power the NAS down and stop writing to it. We image each member before any reconstruction happens. If you do have a verified, current backup, a monitored rebuild is standard practice.
How long does NAS data recovery take?
It depends on what each drive needs. Each drive gets the turnaround for its own pricing tier: 2-4 weeks for file system recovery, 3-6 weeks for firmware repair, and 4-8 weeks for a head swap.
Do you need my entire NAS chassis?
Usually just the drives and any encryption keys or credentials. Modern software RAID (ZFS, mdadm, Btrfs) stores array geometry in on-disk metadata, so physical slot order is not a strict requirement for recovery. We still recommend labeling slots during removal as a best practice.
How is NAS recovery priced?
We price transparently: per-member imaging for logical/firmware issues, an array reconstruction line item, and mechanical member work only when needed. If we recover nothing, you owe $0.
Can I recover a failing NAS over the network using SSH?
Not safely. Recovery software run over SSH reads the drives through the NAS operating system, and it has no per-head control over how a failing drive gets read. Sustained reads like that can push a marginal drive into mechanical failure. Power the NAS down and have the drives imaged on PC-3000 or DeepSpar hardware before anyone tries a reconstruction.
Can you recover a NAS encrypted by Deadbolt or QLocker ransomware?
Sometimes. If a Btrfs or ZFS snapshot from before the attack survived, the data it points to is still on the disks, and we can read it from the cloned members. We image every member, look for snapshots taken before the infection, and pull the files out of them. Without a surviving snapshot, the blocks the attack freed are free space the NAS can reuse. What comes back then depends on how much the NAS wrote afterward.
My NAS uses SMR (Shingled) drives. Does that affect recovery?
Yes. Sustained rebuild writes can run a drive-managed SMR drive out of media cache, and it can stall long enough for the NAS to drop it even though the drive is physically healthy. That event can also damage the drive's second-level translator. If it does, that member needs a firmware repair before we can read its data.
Can you recover data from a WD Red drive with a Module 190 translator failure?
Yes. On Western Digital drive-managed SMR drives, the second-level translator is Service Area module 190. When it's damaged, the drive reads zeros in every sector. ACE Lab's procedure for the PC-3000 is to write the original module 190 back, lock user-area writing so the translator stops changing, and then read physical blocks (PBA) in Data Extractor through the active utility.
How much does it cost to recover a Synology NAS with a crashed NVMe read-write SSD cache?
When an NVMe drive acting as a dirty write cache drops off the PCIe bus, its uncommitted writes are permanently lost. What comes back is whatever the hard drive members hold. Per-member imaging runs from $250 to $600–$900 per drive for firmware-level work, plus $400-$800 for array reconstruction. The evaluation is free, and if we recover nothing, you owe $0.
Will running btrfs check --repair fix a crashed Synology volume?
No. The btrfs-check manual says not to use --repair unless a developer or an experienced user tells you to. Btrfs is copy-on-write, so older generation tree roots survive on disk. A repair run modifies the B-tree structures and overwrites them. We never run it. We assemble the members offline from the clones and pull the files out with read-only tools such as btrfs-find-root and btrfs restore.
Do you recover data from arrays built on Dell PERC or HP SmartArray controllers?
Yes. Dell PERC and LSI/Broadcom MegaRAID controllers write their array metadata to the member drives, in a variant of SNIA DDF on the trailing sectors. HP Smart Array writes a proprietary RAID Information Sector to reserved sectors at the start of each drive. Either way, the geometry is still on the disks when the controller dies. We image each member, read the stripe size and parity rotation from that metadata or work them out from the raw images, and reconstruct the array offline.
Why do you pull NAS drives instead of imaging the array over the network?
Network imaging (SMB, NFS, iSCSI, or SSH-based recovery tools) reads through the NAS operating system, and it has no per-head control over how a failing drive gets read. On a physically weakening drive, those sustained reads push it toward mechanical failure. Pulling the drives lets us image each member on PC-3000 Portable III or DeepSpar Disk Imager hardware. The DeepSpar Disk Imager handles each head differently depending on how degraded it is, and it runs customizable read algorithms. The clones go to fresh destination media. Network protocols can't do any of this.
Two drives in my RAIDZ2 or RAID 6 array failed. Can the data still come back?
RAID 6 and ZFS RAIDZ2 carry dual parity, so they survive two failed members. We image every surviving member before any reassembly. On ZFS we read each member's vdev labels and uberblocks with zdb -lu against the member's block device, then import the pool read-only (zpool import -o readonly=on). On Dell PERC and HP Smart Array controllers, the array geometry is written on the member drives, so we read it from the clones.
Do you recover Drobo BeyondRAID, unRAID, or other proprietary NAS architectures?
Yes. Drobo BeyondRAID is genuinely proprietary block-level virtualization mapped by a Data Allocation Table, and standard mdadm or LVM tools can't read it. The clones go through software that parses the DAT directly from the raw images. unRAID doesn't stripe data. Each data disk holds a complete XFS, Btrfs, or ZFS filesystem, so a healthy disk mounts by itself. Synology Hybrid RAID is standard mdadm plus LVM, so we reassemble it from the clones with standard Linux tools. We don't need the original chassis for any of these. We rebuild the array from the metadata on the disks.
How far back can you recover deleted files from Btrfs or ZFS snapshots on a NAS?
Only as far back as the snapshots that still exist. Data referenced by a surviving Btrfs or ZFS snapshot stays on disk, and when the snapshot is intact we mount it read-only on the clone set and extract that generation. Once a snapshot is deleted, blocks that only it referenced become free space the NAS can reuse. Stop writing to the NAS immediately after a deletion.
Why do you refuse to use the NAS's built-in Repair or Rebuild option, even on a healthy-looking array?
Because a rebuild on a degraded array reads every surviving member end to end under sustained load, and a drive that was marginal beforehand can fail mid-rebuild. The risk is highest on consumer NAS arrays populated with drive-managed SMR drives such as the Western Digital Red WD20EFAX, WD30EFAX, WD40EFAX, and WD60EFAX. Rebuild writes exhaust the drive's CMR media cache and force shingle-band rewrites that stall the drive for tens of seconds, and the array ejects it as dead mid-rebuild. Our policy is the same every time. We power down at intake, image each member, and reconstruct the array from the clones. We never touch the Repair button on the vendor interface.
Is Synology SHR a proprietary RAID format that only Synology can read?
No. Synology Hybrid RAID (SHR) is a management layer that runs on standard Linux utilities: mdadm for RAID parity, LVM for volume management, and Btrfs or ext4 for the filesystem. Any Linux workstation can reassemble an SHR array by reading the mdadm superblocks, activating the LVM volume group, and mounting the filesystem read-only. The claim that SHR requires Synology hardware or manufacturer partnerships is marketing fiction.
Do data recovery labs need manufacturer partnerships to recover NAS devices?
No. NAS appliances from Synology, QNAP, TrueNAS, and Asustor run on open-source software stacks: Linux mdadm, LVM, Btrfs, ext4, and OpenZFS. Recovering them takes forensic parsing of those open-source formats, and nobody needs secret vendor knowledge to do it. What separates one lab from another is whether it diagnoses the fault accurately, publishes its prices, and images the drives in-house on its own hardware.
What brand-specific hardware risks should I know about before shipping my NAS?
Each NAS brand has its own enclosure-level risks. On Synology Plus units, when an NVMe drive acting as a dirty write cache drops off the PCIe bus, its uncommitted writes are permanently lost. The hard drive array is left with an incomplete Btrfs filesystem. QNAP keeps the configuration database that maps storage pools to the mdadm arrays on partition 1 of the member drives. When a failed firmware update corrupts partition 1, the interface reports the pools as empty or uninitialized, while the user data on partition 3 is intact. WD My Book and My Passport USB external drives apply always-on AES in the JMicron or Symwave USB-to-SATA bridge chip. Shuck one and you get ciphertext, even if nobody ever set a password. A drive with the optional SATA 3.3 Power Disable feature also won't power up on a supply that drives 3.3V on pin 3. WD My Cloud NAS units are different. They run embedded Linux on mdadm and ext4 with no bridge-chip encryption, so unless the user turned on software volume encryption, the ext4 data is plaintext and mounts directly in a Linux recovery rig. My Cloud Home is different again. It renames files to 64-character hex content IDs and keeps the original names in a SQLite index.db. Buffalo TeraStation units enter Emergency Mode after firmware corruption on the boot partition. XFS is sensitive about its journal, so we do the replay offline. TerraMaster TOS firmware corruption can leave the interface unable to recognize existing arrays, and then it prompts you to initialize the drives. That prompt is dangerous, because saying yes to it can overwrite your data.
Can you recover a NAS when mdadm superblocks are missing or overwritten?
Yes. Where the superblock sits depends on its version. Per md(4), version 0.90 goes in a 64K-aligned block that starts at least 64K and less than 128K from the end of the device. Version 1.0 sits between 8K and 12K from the end, and version 1.1 sits at the start. Version 1.2, the modern default, sits 4K from the start. When the superblocks are missing, we find the data offset by scanning for ext4, XFS, or Btrfs signatures. We never use mdadm --create on recovery targets, because it writes new metadata to each device. We read the existing superblocks with mdadm --examine, then start the array read only with mdadm --assemble --readonly.
Why is my deduplicated TrueNAS or QuTS hero ZFS pool so slow after an import?
OpenZFS deduplication creates a Deduplication Table (DDT), and holding it in ARC takes roughly 1 to 5 GB of RAM per 1 TB of deduplicated data. The DDT is stored on disk and read on demand, so a pool whose DDT does not fit in RAM still imports, but iXsystems documents that loading the table on demand can take days after an import or reboot, and every deduplicated write or deletion becomes a random disk read in the meantime. That slow-motion load reads like a pool that will not come back. Reading existing data doesn't need the DDT, so on undersized hardware we do a strictly read-only import (zpool import -o readonly=on).
Is it safe to run xfs_repair -L on a Buffalo TeraStation array I assembled on a Linux workstation?
No. The -L option makes xfs_repair zero the log even if it's dirty. The xfs_repair manual says the metadata updates in progress at the time of the crash will be lost, and that -L should only be used as a last resort. A Buffalo TeraStation in Emergency Mode hasn't reached that point. Image each member first, assemble the clones with mdadm --assemble --readonly, then look at the log with xfs_logprint before deciding anything. If the log holds partial transactions, we read the filesystem with xfs_db opened read-only (-r) instead of zeroing anything.

As Featured In

Ready to recover your NAS array?

Free evaluation. No data = no charge. Mail-in from anywhere in the U.S.

(512) 212-9111Mon-Fri 10am-6pm CT
No diagnostic fee
No data, no fee
4.9 stars, 1,837+ reviews